

Agent credit costs are variable. The same agent might cost 2 credits for a quick question and 200 for a deep research task. You pay for what the agent actually does, not a fixed per-message price.
What a credit is worth
1 credit = $0.005
$1 buys 200 credits.
Model calls bill at cost
Divide the model cost by $0.005: a $0.03 model call is 6 credits.
What you pay for
An agent chat is billed in real time, and its total is the sum of four things.
Some runs add a fifth line: if the agent searches your Company Brain, each search is charged to that run and shown as Brain. A search is priced on the embedding and ranking work it does, so it is typically small next to the model cost of the same task.
Chat & Reasoning: model tokens
Chat & Reasoning: model tokens
Priced on the tokens each message uses, converted from the model’s cost at $0.005 per credit. Three things drive it:
- The model you pick. Faster, smaller models cost less per token than frontier models. See AI Models.
- Conversation length. Every message carries the earlier conversation as context, so longer chats cost more per message.
- How many tools are connected. Each tool adds its definition to the prompt, which adds tokens.
Tool Calls: 1 credit per connector call, some charge more
Tool Calls: 1 credit per connector call, some charge more
Every successful connector tool call costs at least 1 credit. Failed calls are not charged.
- Reading and writing to apps like Slack, Google Sheets, and Gmail costs that 1 credit and nothing more.
- Tools that enrich or fetch external data, such as Apollo lead enrichment or Firecrawl web scraping, add their own charge on top.
Compute: active processing time
Compute: active processing time
5 credits per session-minute of active processing, rounded to the nearest whole credit, with a minimum of 1 credit per response.Waiting for your reply costs nothing; only active processing time counts. Enterprise customers running Gumloop in their own VPC are not charged for compute at all, since it runs on their infrastructure.
Orchestration Fee: 8% of the rest of the run
Orchestration Fee: 8% of the rest of the run
Example: Researching a lead
You ask an agent to research a sales lead with Apollo, then summarize whether they are a good fit:
Had the agent only read a Google Sheet and summarized it, the tool side would be just the 1 base credit, since Google Sheets charges nothing extra.
Plans and included credits
Every new account starts with a 14-day free trial of Pro. The trial requires a card, is a one-time offer per customer, and rolls into a paid Pro subscription when it ends unless you cancel first.
To cancel a trial or a paid plan, open Manage Subscription on your Usage & Limits page (Settings > Organization > Usage & Limits); see Subscription Management. Cancelling during the trial stops the card from being charged when the trial ends.
Running out of credits
Enable credit overage on your Usage & Limits page to keep running past your monthly credits, billed at $0.005 per credit. Pro overage is always capped. The default ceiling is 1,000,000 overage credits per billing period ($5,000), and you can set a lower cap on that page. Agents stop once the cap is reached. Enterprise plans set their own cap, or can choose to run uncapped. To turn it on, click Enable Credit Overage on Usage & Limits, set the Overage Cap, and click Enable Overage. To change the cap later, click Manage Credit Overage on the same page.Billing questions
For invoices, payment methods, procurement, taxes, or charges you do not recognize, email accounting@gumloop.com. Self-serve invoice downloads are available in the billing portal; see Subscription Management.For Enterprise credit allocations and account questions, use the account-team contact provided to your organization. For invoices and payment paperwork, use the accounting address above. Product and technical questions go to support@gumloop.com or open a ticket.
Where to see what a chat cost
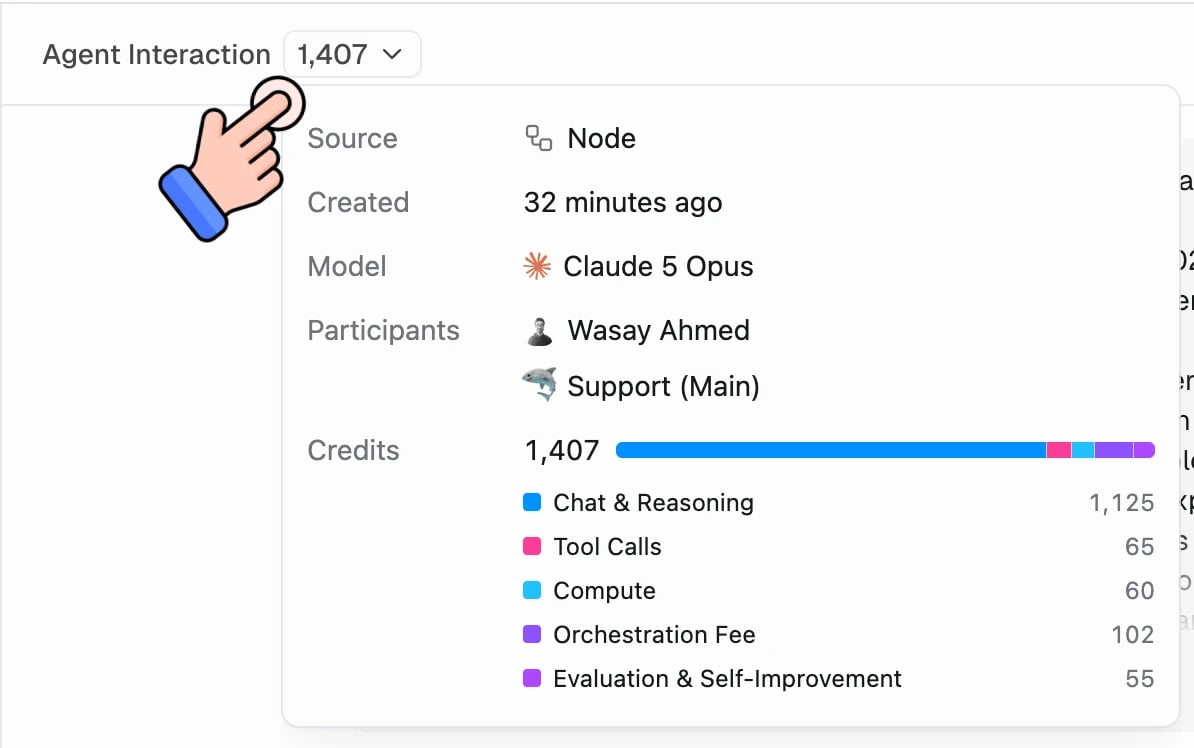
The running cost of a conversation appears next to the chat’s name in the chat header and updates live. For the full breakdown, select that credit count to open the chat’s details drawer. Alongside the chat’s source, trigger, creation time, models, and participants, it lists one row per credit type the chat was actually charged for: Chat & Reasoning, Tool Calls, Compute, Orchestration Fee, Brain (Brain searches the agent ran), Evaluation & Self-Improvement, Voice (time spent on a Talk mode call), Flows, Subagents, or Other.Credits that were waived rather than charged (BYOK model calls, and compute for VPC organizations) still appear, struck through and labelled Free, so you can see what the run would have cost.
Tracking usage over time
Insights dashboard
Insights dashboard
The Insights dashboard (Settings > Organization > Insights) is the best place to see credit spend across all your agents. It shows total credits spent for the selected period, a credit spend and volume chart, and leaderboards of your top agents and models.The tabs let you dig deeper: Models breaks spend down by AI model, and Credit Explorer lets you slice usage.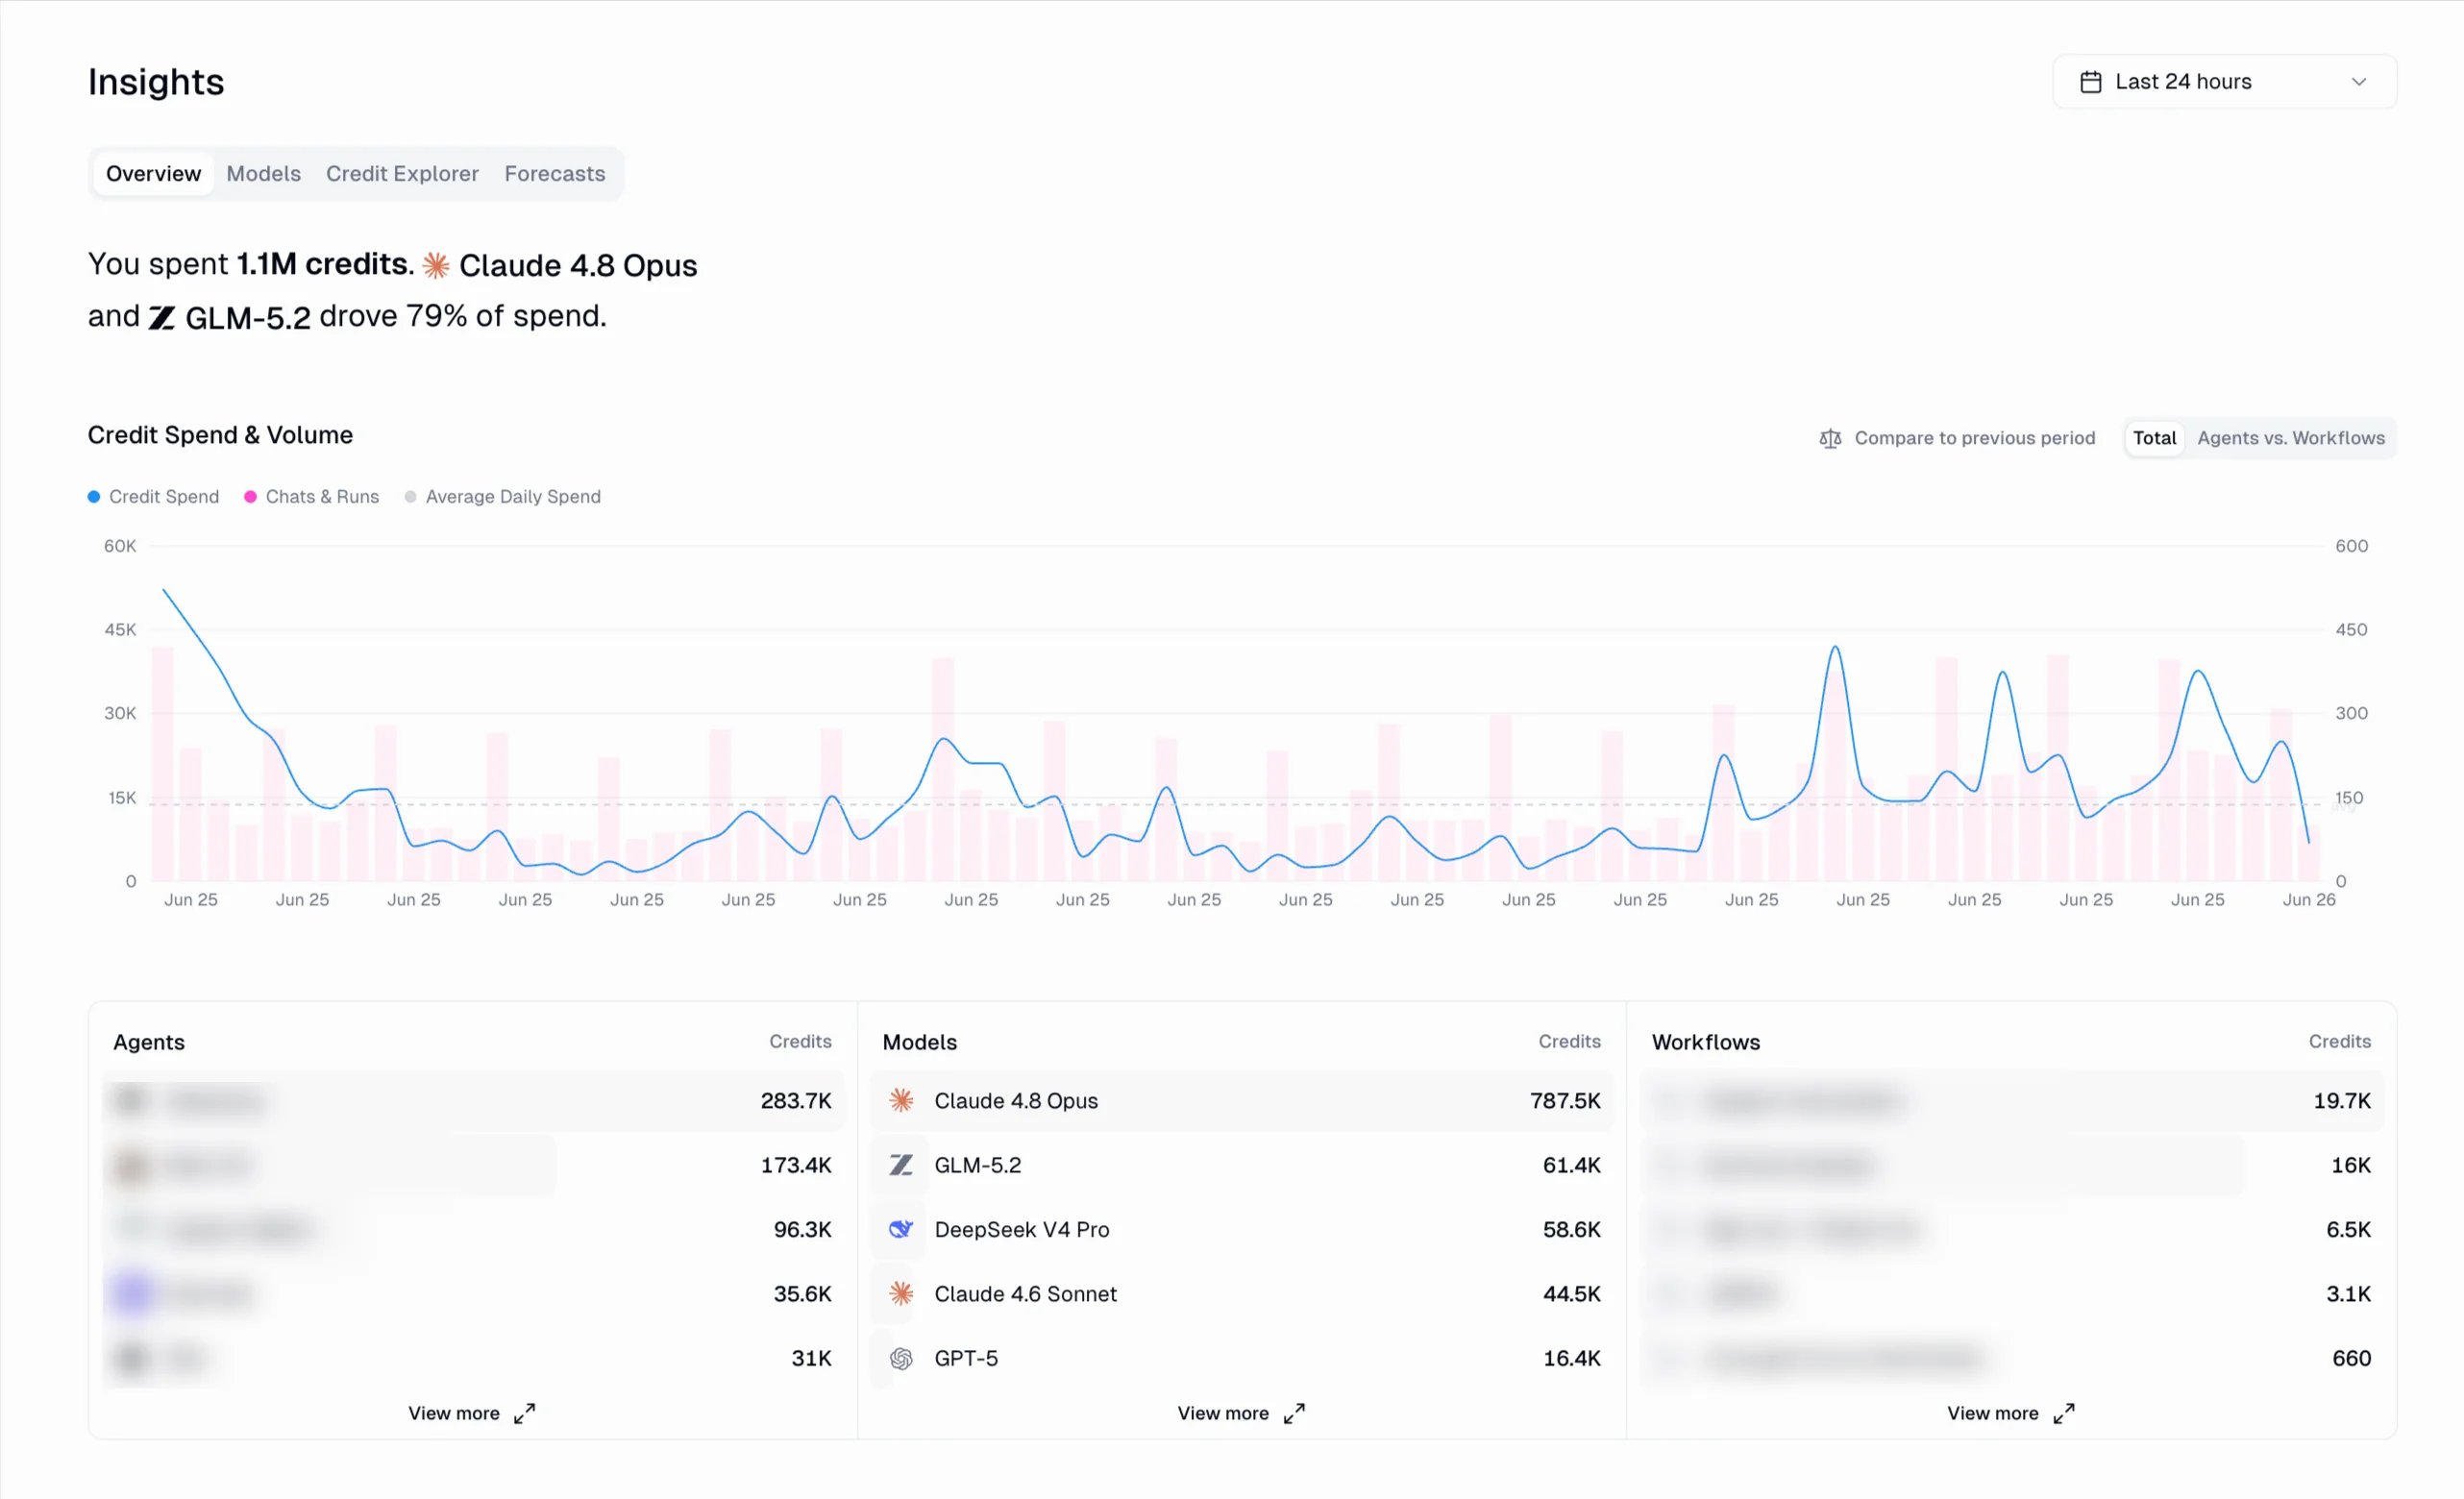
The Insights dashboard is an Enterprise feature.
Credit logs
Credit logs
For a transaction-level view, open Settings > Profile > Usage & Limits:
- Grouped view (default): one row per agent conversation, showing its total. Expand a row to see the individual charges inside it.
- Detailed view: one row per individual charge, with the exact type and amount.
Ask the analytics agent
Ask the analytics agent
You can also ask about credit usage in plain language. The analytics agent answers questions like “how many credits did we spend in the last 30 days, broken down by user?” and returns tables, charts, or CSV exports. It is available on the Insights page (Settings > Organization > Insights) and in Slack.
Export
Export
Export credit logs as CSV from Settings > Organization > Data Export for external analysis or compliance.
How do model modes affect cost?
A supported Fast or Ultrafast mode uses higher token rates than Standard. The mode is a setting on the same model, not a separate model choice. See AI models for availability. Current GPT-6 chat models charge 2× Standard token rates for Fast. GPT-6 Astra and GPT-6.1 Sol charge 6× for Ultrafast. Other models and decision calls have their own rates. If the provider serves a request at a different tier than the one requested, you pay the rates for the tier it actually served. Check the task’s credit breakdown for actual usage rather than estimating a fixed price per message.Reducing credit costs
- Pick the right model. Start with the Balanced preset in the model dropdown on the Agent tab. Use Auto when message difficulty varies, and only reach for Smartest when a task needs deep reasoning. See AI Models.
- Bring your own key (BYOK). Eligible model calls on your own provider key use 0 model credits on usage-based pricing (Pro plan or higher). Older pricing policies may apply a discount instead.
- Start fresh conversations. A new chat for a new topic avoids carrying old context that inflates token costs.
- Stay inside the short context window. GPT-6, saved GPT-5.6 models, and Grok 4.6/4.7 charge higher long-context rates once a request’s input tokens pass the short-window boundary (272K and 200K), and the higher rates apply to the whole request. Open the model dropdown in the Agent tab and choose the smaller Context window to stay below the long-context pricing boundary.
- Connect only the tools you need. Every tool definition adds tokens to the prompt.
How BYOK works
How BYOK works
On usage-based pricing, Gumloop runs eligible model calls on your key and charges 0 model credits; you pay your provider directly for the tokens. Older organizations may use a policy that discounts model credits instead of fully waiving them. The table and example below describe usage-based pricing.
Because the model spend leaves your credit balance entirely, agent chats on BYOK carry a 16% orchestration fee instead of 8% (your Enterprise rate plus 8 points, if you have one), calculated on what the run would have been worth.For example, a chat with 400 credits of model usage, 10 of compute, and 15 of tool calls has this Gumloop credit cost:
You cover the model tokens directly with your provider instead.Requires Pro or higher and your own supported provider key. A key applies only to models served by that provider. See AI models for current provider coverage.Add a key from your personal Connectors, or add a shared team key for the whole team. Enterprise admins can set organization-level keys. See AI Models.
Credit notification preferences
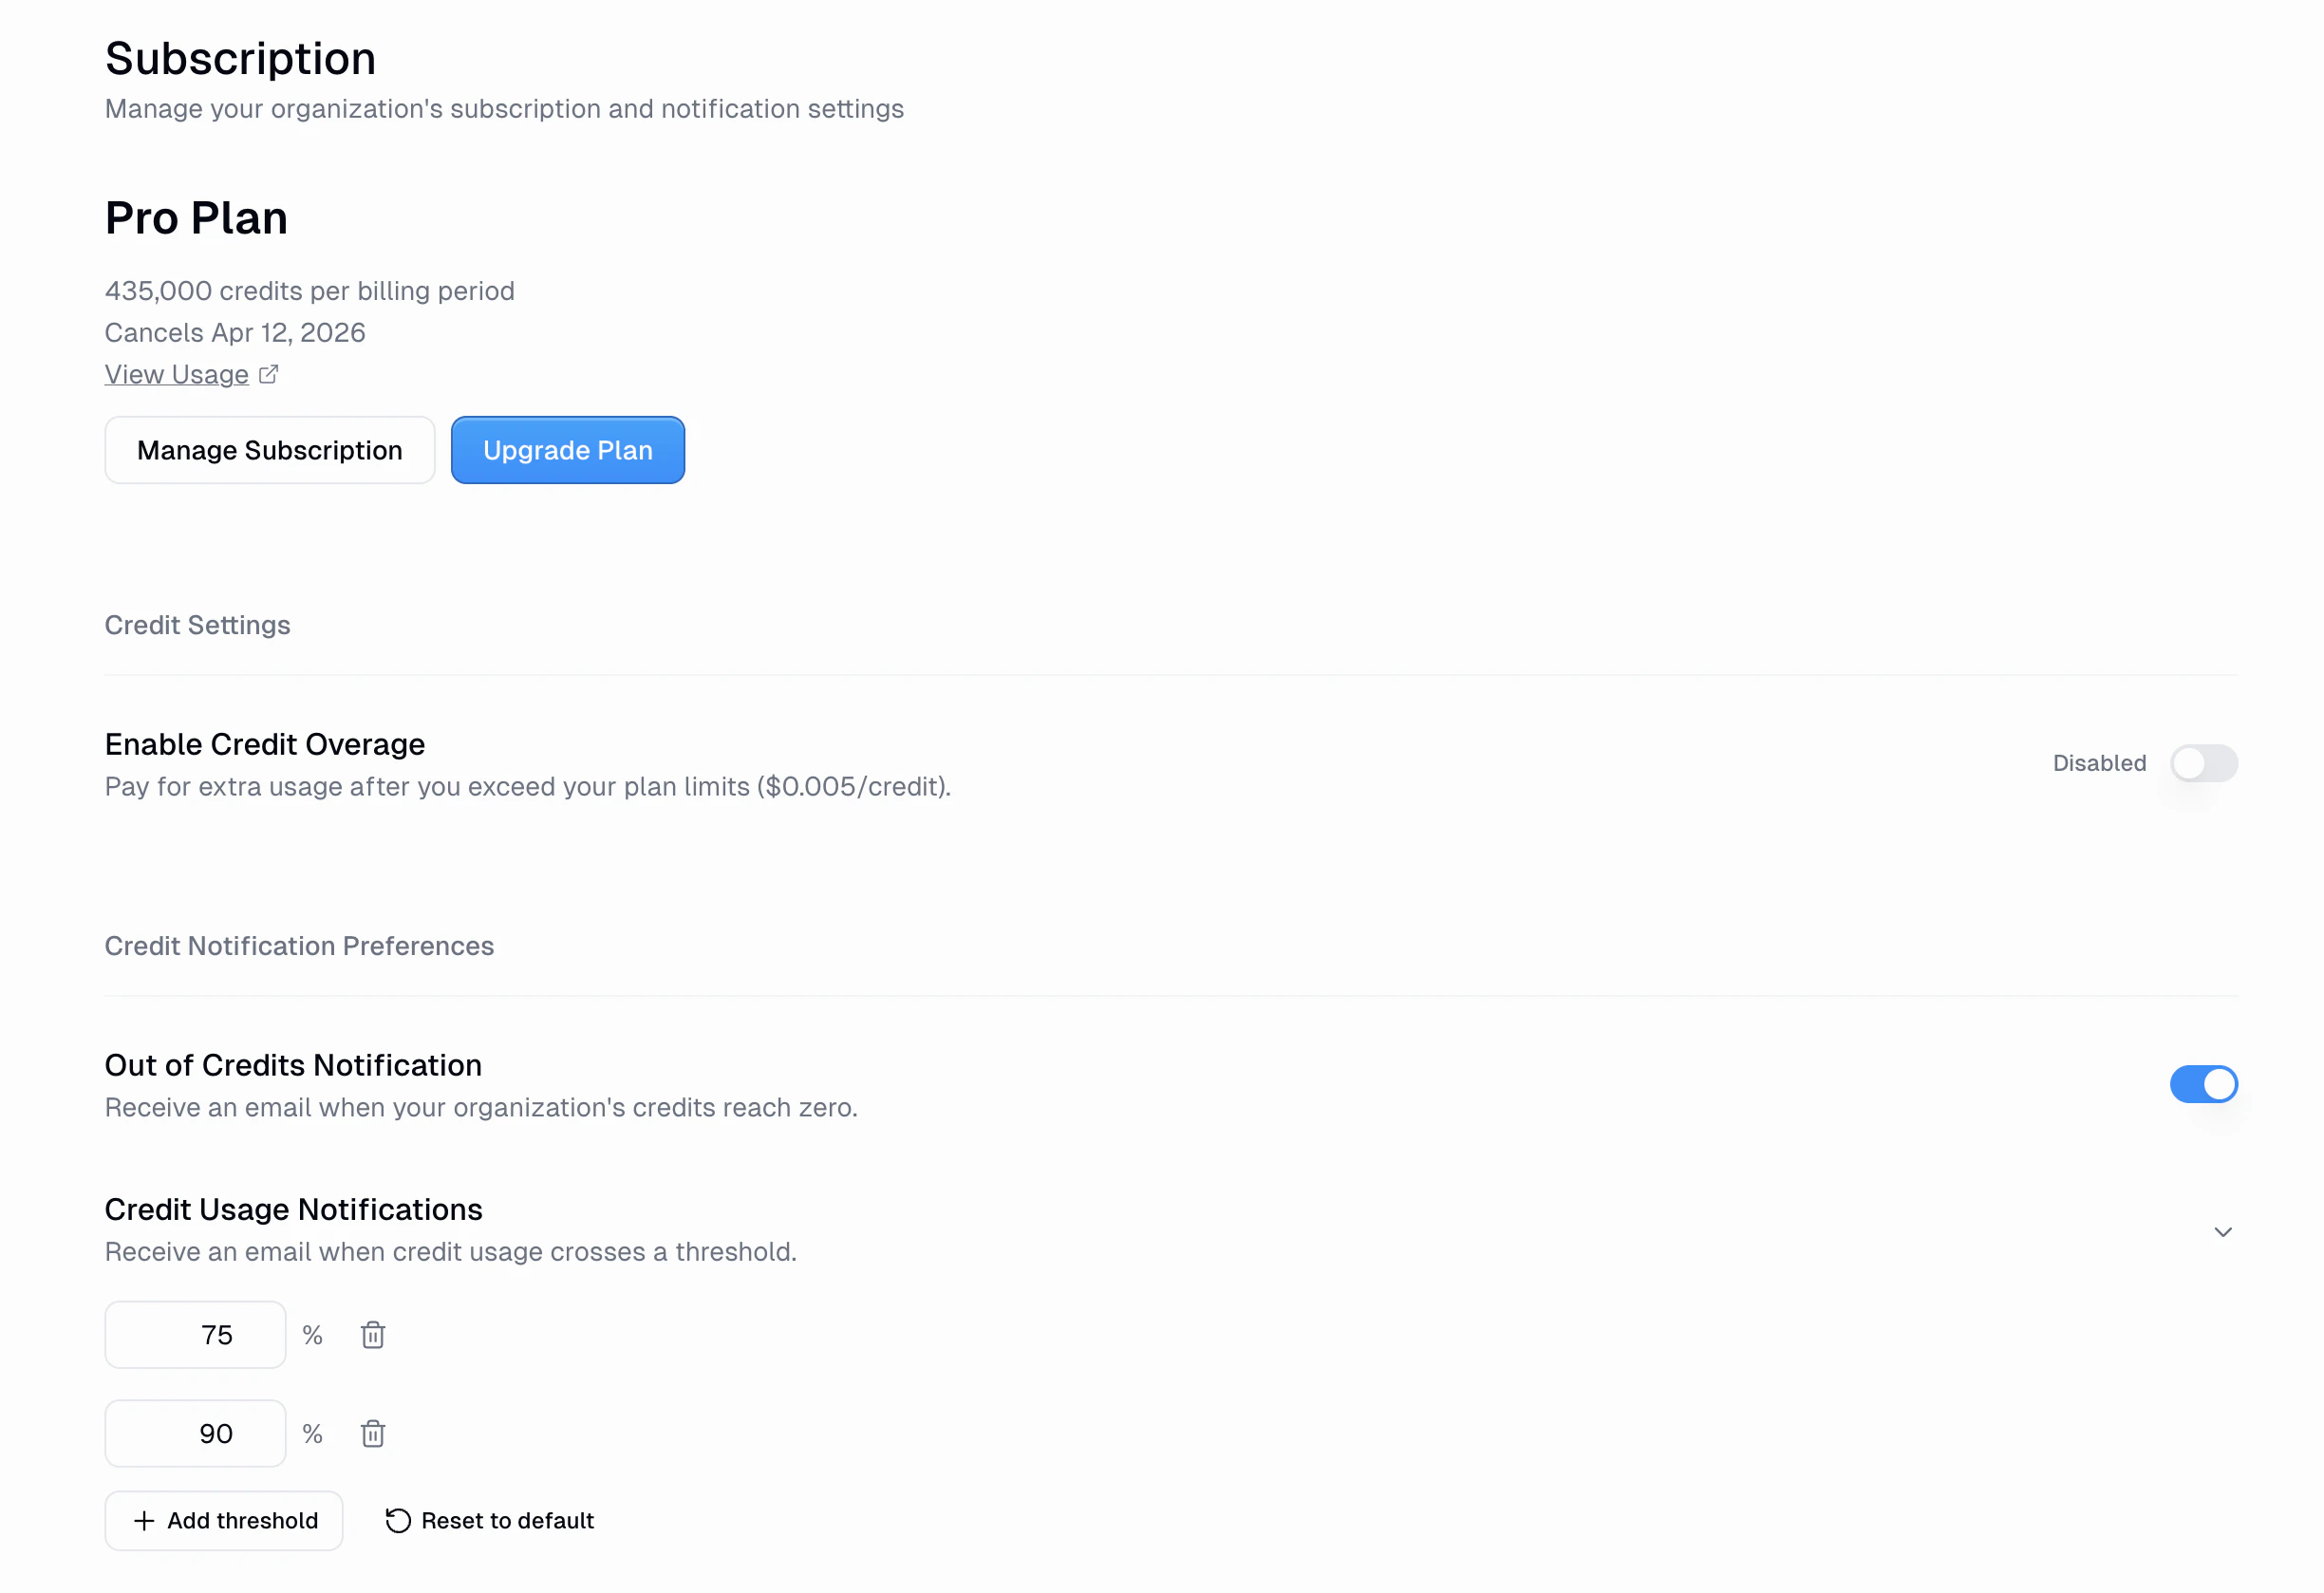
Gumloop can email you when your organization’s credit usage crosses key thresholds. Manage these on your Usage & Limits page.- Out of Credits Notification: an email when credits reach zero. On by default.
- Credit Usage Notifications: an email when usage crosses a threshold. Defaults to 75% and 90%. Add, remove, or reset thresholds as needed.
Per-chat credit warnings
Admins and Security role holders can also set per-chat credit warnings through Custom Roles. When a single chat’s spend crosses a configured threshold, such as 5,000 or 10,000 credits, the agent pauses and creates an Action Request for approval before continuing, so no single conversation can consume an unexpected amount of credits.Voice call costs
Talking to an agent in Talk mode is billed by call time, not by tokens. The voice model, GPT Live, costs about 10 credits per minute of call time, prorated by the seconds you actually talk. The charge accumulates as the call runs rather than landing in one lump at the end, and it appears as Voice in the chat’s credit breakdown.- A call needs credits for the minute ahead, so it starts only if you can cover the first minute and ends if your balance runs out mid-conversation.
- Model calls, tool calls, and compute during the call are billed as usual, in addition to call time.
What do voice messages cost?
Audio messages and voice memos sent through Slack or iMessage can incur a transcription-model charge before the agent responds. That is separate from the agent’s normal model, tool, and compute usage, and from the call-time pricing for Talk mode above. The audio format and your model permissions determine which transcription model can be used. Sending the same recording in a new message can incur another transcription charge.Interactive artifact costs
When you open an interactive artifact or a live Chat Widget that pulls data, its data scripts use Compute. Runtime is billed at roughly 1 credit per 55 seconds, with a minimum of 1 credit per run. The viewer pays, not the creator. Opening it again can run its scripts again and incur another charge. Most scripts finish in seconds, so the typical runtime charge is 1 credit per load.Learn more
AI models
Choose the right model and set up BYOK
Pricing plans
Current plans, included credits, and overage
Billing questions
Email accounting@gumloop.com about invoices, payment, and procurement