

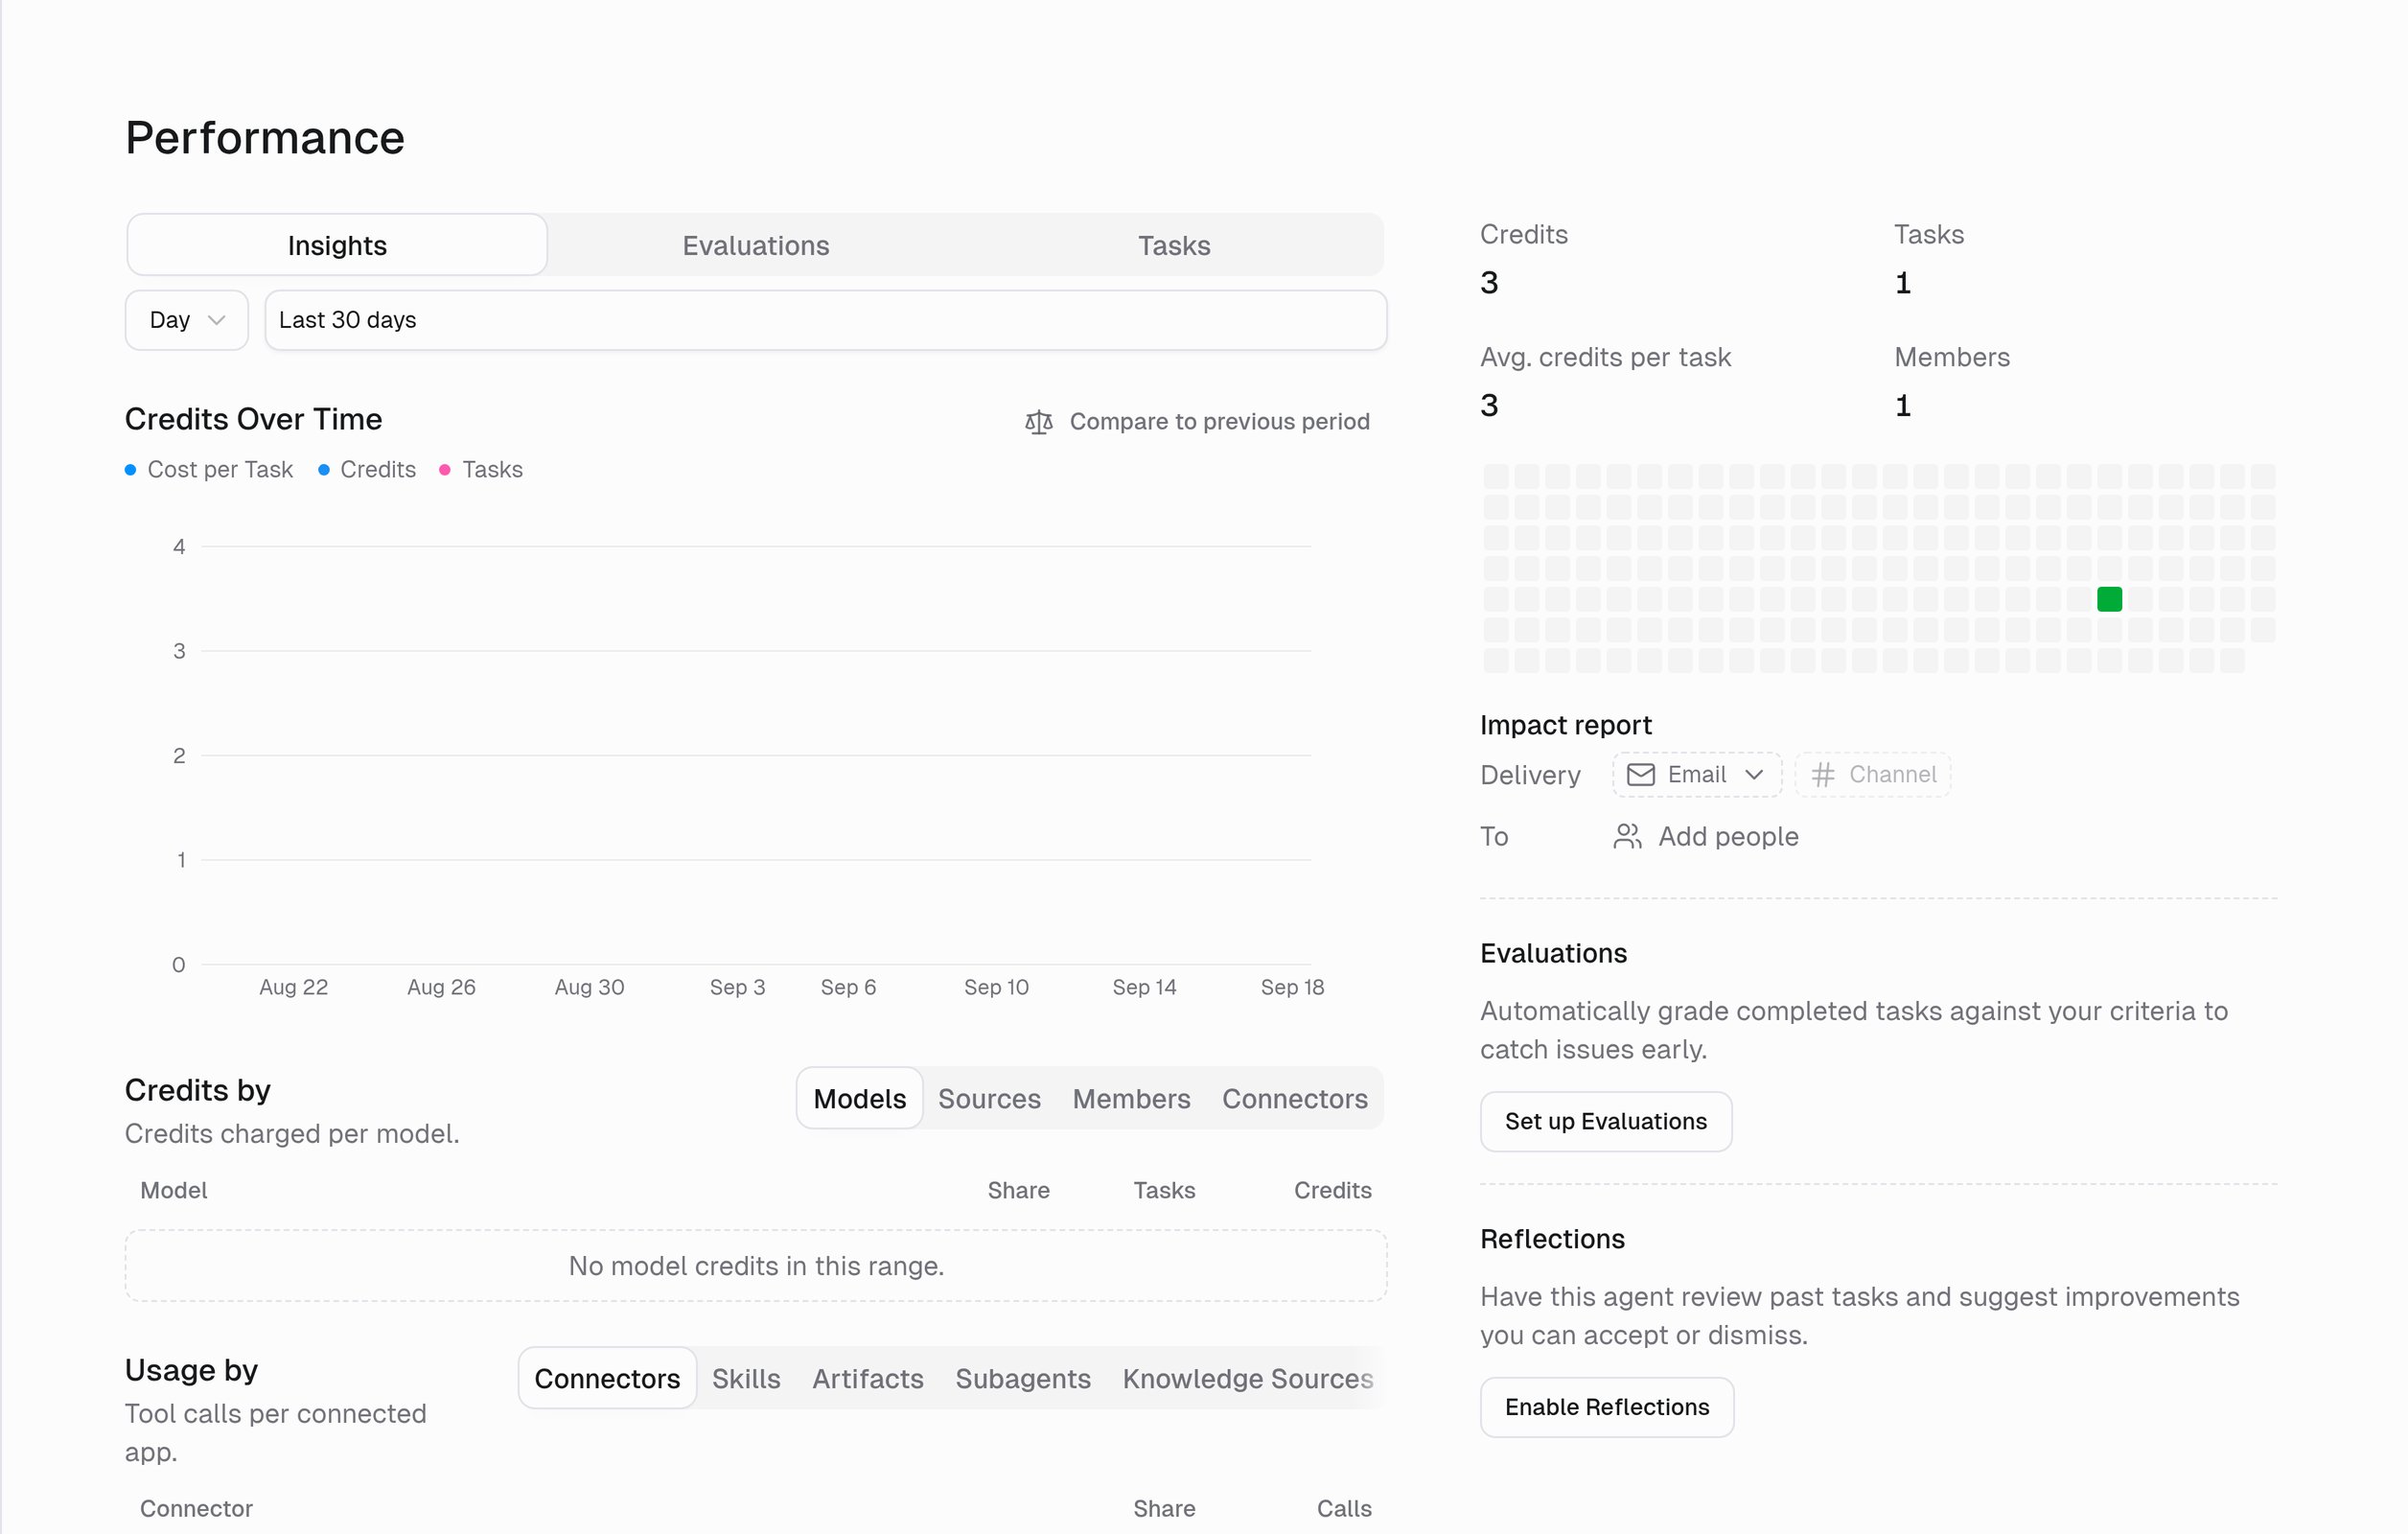
Performance reporting depends on your analytics permissions. Access to a saved conversation also follows Agent access, including your organization’s conversation visibility policy. For organization-wide reporting, see Insights.
Insights
Pick a date range, and optionally Compare to previous period to see the change. The chart’s interval is chosen for you to suit the range, and you can switch to any other interval that still makes a readable chart:
Usage & Credit Trend charts credits and tasks so you can distinguish a rise in spend from a rise in usage. Hover a point to see cost per task.
The overview on the right gives you the headline numbers for the range:
Further down, two breakdown tables:
- Credits by: Models, Sources (where tasks came from, such as a trigger, Slack, or the app), Triggers (credits charged per trigger), Members, and Connectors.
- Usage by: Connectors, Skills, Triggers, Artifacts, Subagents, and Knowledge Sources. The Triggers view lists Runs, Failed, and Last run for each trigger.
Task outcomes
Under the trend chart, Task outcomes charts how tasks ended over time, on the same range and interval as the rest of the tab:Which kinds of tasks cost the most?
Cost vs completion plots each kind of task the agent handles, such as Answer a question or Produce content. Higher means a better completion rate, further right means more credits per task, and a bigger dot means more tasks. Hover a dot to see Tasks, Credits per task, Completed, and Tool calls per task. Gumloop labels tasks shortly after they finish. Why tasks didn’t complete lists the reasons tasks failed, with a count for each. If you can view the agent’s configuration, select a dot or a reason to open the matching tasks on the Tasks tab.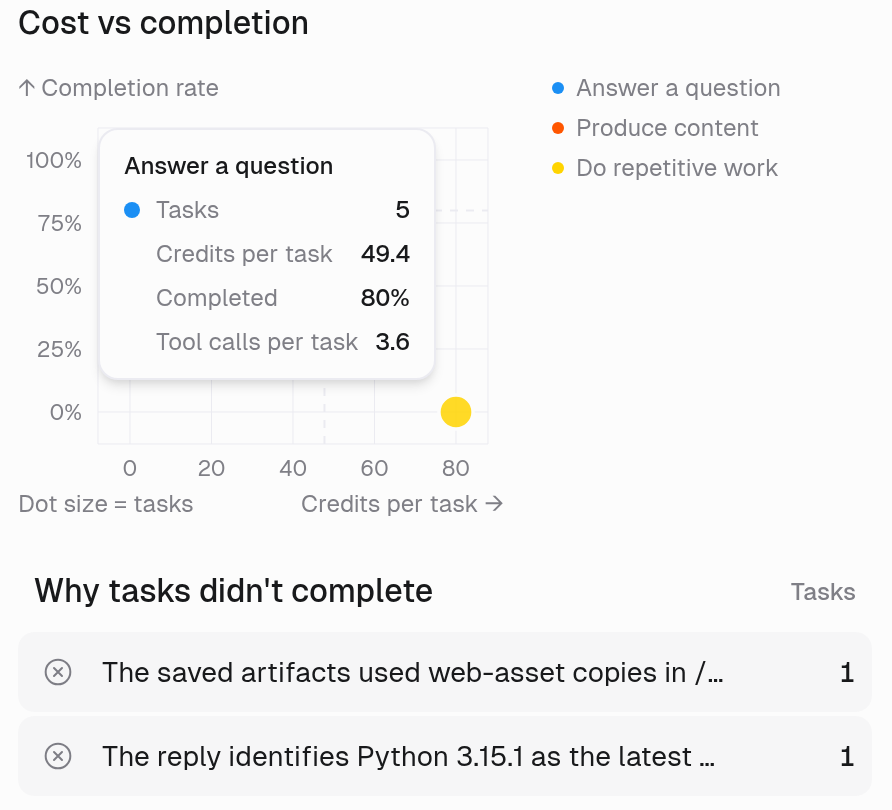
Is a connector failing?
Usage by > Connectors shows each connected app’s Share of tool calls, Failed share, Typical (median) response time, and Calls. Needs reconnect marks a connector whose account you need to refresh.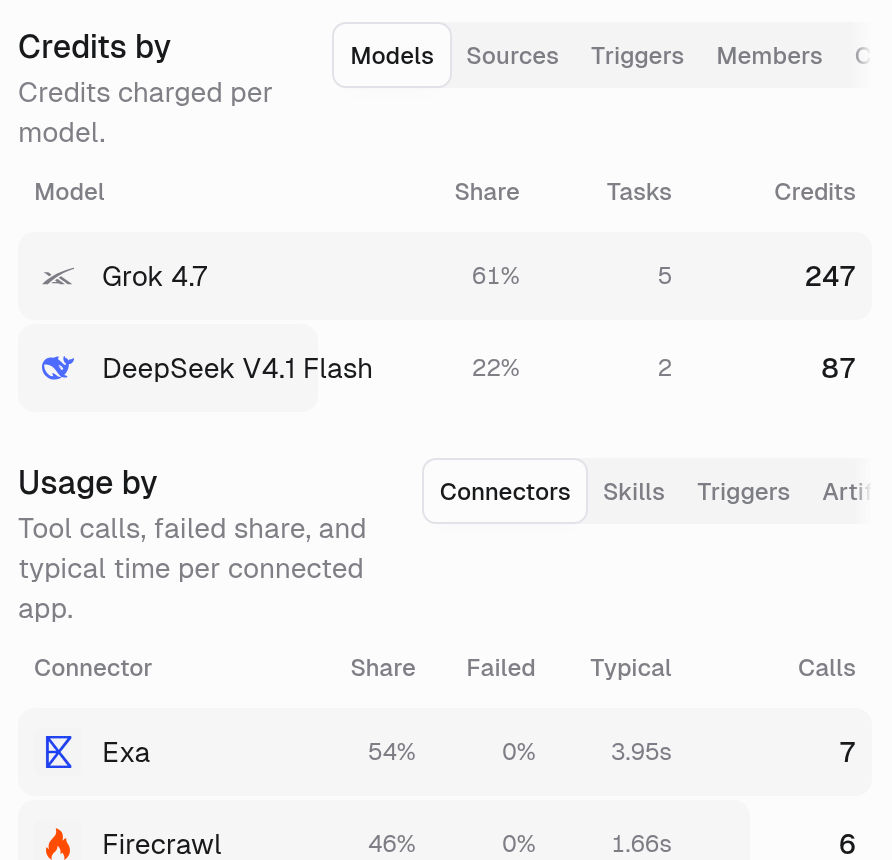
What changed, and what it did to cost
Markers along the bottom of Usage & Credit Trend show when the agent was changed, so you can line a change up against the spend and volume around it. Each marker covers one interval of the chart. Select one to see the changes inside it, newest first, with who made each one:- Agent created
- Model changed: the model it moved to, and the one it came from
- Instructions edited
- Connectors, skills, and knowledge sources added or removed
- Reflections the agent applied. Select one to open the suggestion.
A change made before the agent ran any tasks is marked No tasks yet, since there is nothing yet to compare against.
Impact report
Have Gumloop send this summary out on a schedule, by Email or to a Channel, to the people you add under To. Useful for keeping a team lead in the loop without giving them the builder.Evaluations and Reflections
Both features live in the summary panel on the right of this page, and both are switched on from here:
See the linked guides for criteria, tags, data points, schedules, reports, and API details.
Evaluations tab
Once evaluations are on, this tab shows the grades: how completed tasks scored against your criteria, which ones failed, and the trend over time. That is where you catch a regression after changing the instructions or the model.Tasks tab
Review this agent’s task history to see who started each task, its source, and its credit cost. Open a saved task you have access to when you need to investigate an evaluation result. Filter the list by task label, Failure reason, Date range, and Credits (tasks over a credit amount). Task labels come in two groups, named Kind of work and Area unless your organization renamed them. With analytics access, incognito tasks also contribute to counts and can appear as Incognito Chat. Creator and usage metadata can remain visible, but there is no durable message transcript to open. See Incognito mode.Related
Evaluations
Define criteria and grade the agent’s answers.
Reflections
Let the agent propose its own improvements.
Credits
What the agent is charged for.
Organization Insights
The same picture across every agent and team.